유럽 및 미국 동부 해안에서 큰 재포 (5k + 재포) 경험 느린 빌드 완료, 주위 시작 2am PST / 5am EST.
Behavior : 2am-6am PST 사이에 열린 PR은 느리거나 누락 된 Coveralls PR 의견 또는 상태 검사가있을 수 있습니다.
우리는 문제 및 할당 된 리소스를 확인하여 백그라운드 작업의 백그라운드 작업을 취소합니다. 작업은 명확하고 빌드는 다음 1 시간에서 완료해야합니다.
monitoring
큰 저장소와 문제의 뿌리 원인은 완전히 해결되었습니다. 우리는 몇 백그라운드 작업을 계속합니다. 우리는 계속 모니터링 및 보고서 업데이트.
resolved
이 사건은 해결되었습니다.
postmortem
# 업데이트 : Heavy Repo Builds에 출시 된 주요 성능 최적화
이 최신 사건에 의해 Triggered, 우리는 큰 \를 처리하는 우리의 부호에 중요한 최적화를 풀어 놓았습니다 (aka. "heavy"\) repos \(>=5K 소스 파일 \).
10월 9일(금), 10월 11일(토) 주말에는 평균중량 대비 평균중량 대비 20배 향상을 보여준다. 우리는 최적화를 기대하는 동안 지속적으로 이러한 repos \에 대한 구축 시간을 개선 (그리고 그들에 대한 증가 지연의 사고를 감소), 우리는 우리가 전체 볼륨이 이번 주에 때까지 집계 개선이 무엇인지 모른다.
우리는 성능 향상 토지의 의미를 얻기 위해 모니터링, 그러나 우리가 어떻게 효율적으로 이러한 빌드를 처리하는 방법에 중요한 이정표를 교차하는 희망은 그들이 포즈의 독특한 도전을 받았다.
공식 인시던트 업데이트를 자동 번역했습니다.
Elevated 오류율
시작 2026년 9월 28일 오후 4:03 UTC · 1h 18m
Outage중대한 인시던트
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
우리는 현재이 문제를 조사하고 있습니다.
identified
문제는 식별되고 수정이 구현됩니다.
monitoring
수정이 구현되어 결과를 모니터링하고 있습니다.
monitoring
모든 지역에서 운영. 우리는 더 많은 문제를 모니터링하고 있습니다.
monitoring
우리는 더 많은 문제를 모니터링하고 있습니다.
resolved
이 사건은 해결되었습니다.
postmortem
### 해결: 높은 오류율, 월요일 9월 28, 08:00 에 09:15 PT
**시간**: 약 08:00과 09:12 PST에서 9월 28, 일부 요청은 Coveralls 반환 HTTP 500 오류. Coverage uploads, GitHub webhook 이벤트, 배지 및 적용 페이지가 영향을 받았습니다. 실패는 창의 끝을 향해 첫 번째로 얽혀 있었다. 서비스는 완전히 09:12 PST에 복원되었습니다.
** 원인 **: 우리의 기본 데이터베이스와 용량 문제. 우리는 추가 용량을 가지고, 자동 스케일링을 활성화하고, 우리의 모니터링 트리거를 변경하여이 종류의 문제 재발 할 수 있습니다.
**해야 할 일 **: 영향을받은 경우 : 08 : 00과 09 : 15 PT 사이의 Coveralls에 업로드 된 모든 CI 작업을 다시 실행하거나 새로운 커밋을 밀어. 데이터가 손실되거나 손상되지 않았습니다. 그 업로드는 단순히 토지를하지 않았다.
우리는 혼란에 대해 죄송합니다.
공식 인시던트 업데이트를 자동 번역했습니다.
"Website under heavy load" warning
시작 2026년 8월 11일 오후 7:02 UTC · 2h 8m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
We are currently experiencing occasional "Website under heavy load" warnings.
We believe this is the second wave of an attack we experienced this weekend involving an army of scraper bots which we successfully mitigated. We believe the attacker may have gotten around an initial phase of defense.
Separate from a DDoS attack, these are millions of individual requests coming from over 280K different IP addresses across 12 different countries, so our standard DDoS protection (IP quarantine) does not apply.
We are implementing a second phase of defense and will report updates here.
monitoring
This was the second wave of the attack we experienced this weekend, broadened and tripled in volume. We implemented a second phase of defense which appear to be working and will continue monitoring for the next hour.
resolved
This incident has been resolved.
큰 repos를 위한 증가된 대기권
시작 2026년 7월 15일 오후 5:28 UTC · 5d 0h
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
모든 시스템 완전 기능. 우리는 큰 repos를 위한 증가된 대기권이 다시 확인하고 과잉 요구의 proactively 체포한 근원이 있습니다. 우리는 시간 내에 정상적인 대기 시간을 복원 할 것으로 기대합니다.
monitoring
우리는 75%에 의해 영향을 받는 큐에 트래픽을 감소했습니다. 우리는 아직도 대략 1 시간 안에 큐를 지우기 위하여 예상합니다. 우리는 여기에 업데이트합니다. 사용자가 3-10x 정상적인 일일 업로드를 업로드 한 큰 재포 (>=5K 소스 파일)로 일시적으로 일시적으로 일시적으로 일시적으로 사용되었는지 생각하면 [email protected]에서 우리에게 도달하고 더 많은 일시 중지를 피하기 위해 다음 단계를 확인하고 알려줍니다 (https://coveralls.io/pricing에서 사용 Add-Ons 참조).
monitoring
우리는 더 많은 문제를 모니터링하고 있습니다.
monitoring
우리는 proactively 감시자를 계속하고 큰 repo 큐를 삭제합니다.
우리는 주말에 더 긴 기간 해결책에 일하고 완료할 때 이 문제점을 위한 postmortem에서 그것에 관하여 포스트할 것입니다.
우리는이 사건이 우리가 위 평균 대기권을 가진 큰 repo queueues가 있기 때문에 열립니다.
monitoring
대기 시간은 큰 저장소에 대 한 약 30%에 의해 상승. 우리는 우리가 더 장기적인 해결책을 실행할 수 있기까지 mitigate를 감시하고 하는 것을 계속합니다.
resolved
이 문제는 주말에 해결되었습니다. 우리는 수정 된 큐에 높은 지연을 모니터링 할 것입니다.
공식 인시던트 업데이트를 자동 번역했습니다.
큰 repos를 위한 증가된 대기권
시작 2026년 7월 10일 오후 3:00 UTC · 2d 23h
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
identified
우리는 배경 작업 큐에 트래픽을 높이기 때문에 더 큰 저장소 (5K + 소스 파일)에 대한 대기 시간을 모니터링하고 있습니다. 우리는 2x 평균 트래픽보다 더 많은 것을 일시 중지 할 것입니다. 일반적으로 인구를 명확하게하기 위해 큐를 허용하기 위해, 다음 한 번 큐를 삭제했습니다. 당신이 당신의 repo를 생각하면 그 일시 중지 중 하나가있을 수 있습니다, 두 가지:
1) [email protected]에 저희에게 도달하고 우리는 확인합니다; 그리고
2) 사용 추가를 구입 고려하여 작업이 공정한 사용, 또는 최대 성능에 대한 격리 된 인프라와 엔터프라이즈 플랜을 훔치는 것은 아닙니다. https://coveralls.io/pricing
monitoring
우리는이 상황을 모니터링하고 있습니다. 지연은 훨씬 감소하지만 여전히 상승. 우리는 완전히 정상에 복원 될 때이 사건을 닫습니다.
resolved
이 사건은 해결되었지만, 우리는 그 해결을 얻은 일요일 밤 / 월 아침 (US PDT)의 악한 사건을 방아쇠를 내렸습니다. 전체 RCA에 의해 확인하려면, 우리는 프론트 라인 요청을 처리하는 개인 웹 서버를 묶는 큰 repo 업로드의 deluge를 믿는다. 각 웹 서버는 자체에서 복구 할 수 있지만 볼륨이 모든 서버가 결국 영향을 받지 못했기 때문에 요청이 504 오류로 대부분의 요청을 거부 할 수있는 짧은 창 만 허용했습니다.
우리는 우리가 무슨 일이 일어나고 그것을 방지하는 방법에 대해 더 많은 것을 이해 할 때 포스트 모뎀을 게시 할 것입니다.
공식 인시던트 업데이트를 자동 번역했습니다.
큰 repos를 위한 증가된 대기권
시작 2026년 7월 7일 오후 4:43 UTC · 11h 56m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
우리는 더 큰 저장소 (5K 소스 파일과 더 큰)에 대한 증가 지연 시간을보고있다. 사이트가 완전히 운영되는 동안, 당신은 당신의 repo가 >=5K 소스 파일이 있었다면 당신의 PR에 완성 된 빌드 페이지 및 적용 알림을 받기 전에 지연을 경험할 수 있습니다. 우리는 모니터링 하 고 어떤 outlier repos를 일시 중지 됩니다 (불평, 과도한 사용) 큰 repo 큐에 일반 트래픽을 허용 하기 위해.
monitoring
우리는 너무 offload some outlier repos가있어 무거운 저장소로 사용자의 일반 대중을 명확하게합니다. 이 세 가지가 있습니다. 우리는 일반적으로 queues가 명확하게 된대로 그 repos에 처리를 다시 시작합니다.
오늘 일시 중지 된 과도한 트래픽을 가진 저장소 중 하나가 될 수 있다고 생각한다면, 그냥 도달하고 우리는 당신이 알고있을 것입니다 : [email protected].
우리는 오후 6시 PDT에 의해 일반적인 큐를 명확하게합니다. 그 후 우리는 outlier에 대 한 처리를 복원 하 고 10p-12a PDT 사이 이 저녁에 의해 완료 될 것으로 예상.
resolved
큰 저장소에 대한 증가 지연은 일반 대중을 위해 해결되었습니다. 우리는 내일 AM에 의해 완전히 명확해야 할 세 가지 아웃 런을 취소합니다.
공식 인시던트 업데이트를 자동 번역했습니다.
Increased latency for large projects
시작 2026년 5월 18일 오후 4:41 UTC · 9d 23h
Pending
영향을 받은 구성 요소
Coveralls.io Web
identified
We have received reports of increased report latency for larger projects (5K file and up). We are doing our best to clear the background job queues for these projects. If you have one of these projects, feel free to reach out and we'll check status for you.
monitoring
A fix has been implemented and we are monitoring the results.
monitoring
We are still receiving reports of latency for large projects and are seeing backlogs of background jobs in queues dedicated to large repos (5K+ source files). We may pause some outlier repos with excessive numbers of jobs in order to clear general traffic. If you believe you may have been paused, reach out and we'll let you know.
monitoring
We are keeping this incident open as we continue monitoring.
monitoring
We have moved all repos with more than 300 jobs in queue to dedicated queues for processing. These 7 repos were responsible for 75% traffic in our heavy repos queue. This move allows us to provide normal processing times for non-outlier repos and dedicated resources to outlier repos. Outlier repos by their job volume will still take longer to clear. If you believe you may be one of these outlier repos, please reach out and we'll confirm and give you an idea of when your jobs will be processed. If you'd like faster processing, we can also pause processing on older job, for instance, anything older than 1 hour (or 2 hours, or 3 hours) ago.
monitoring
We continue to monitor background processing queues for larger repos (5K+ files), as we continue offloading incoming jobs from the outlier repos whose volume led to the original backlog. If you think you may have been paused as one of these repos with outlier-level volume, please reach out to us at [email protected] and we'll confirm status and get you an ETA on when your remaining jobs will be processed.
monitoring
We are continuing to monitor for any further issues.
monitoring
We've cleared the backlog of background jobs for larger projects from our heavy project queues, with the exception of nine projects whose volume continues to exceed our daily fair use thresholds. Those nine have been redirected to secondary and tertiary queues that drain only after the primary queue is clear. Most of their jobs have now been processed, but a few projects generate more jobs than a normal day + overnight cycle can drain, so some backlog remains. We're continuing to work those queues down manually. If you think one of your projects may be affected, reach out to us at [email protected] and we'll check status for you.
resolved
We are closing this incident. Our main background processing queue for larger repos has had no backups in 48 hrs. We will continue monitoring for recurrence.
Unschedule maintenance
시작 2026년 5월 10일 오후 2:44 UTC · 27m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
We are currently investigating an issue with an apparently expired SSL cert. Our orchestration layer shows no issue with certs so we need to dig deeper.
resolved
This incident has been resolved.
Service outage (RESTORED, MONITORING)
시작 2026년 2월 24일 오후 10:52 UTC · 2d 23h
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
We are currently investigating this issue.
investigating
We are continuing to investigate this issue.
identified
The issue has been identified and a fix is being implemented.
identified
Outage will be extended for at least several more hours.
To avoid further disruption to your CI workflows, we recommend employing the fail-on-error: false input option available with all official coveralls integrations.
See: https://docs.coveralls.io/integrations#official-integrations.
Official Integration: fail-on-error option
- GitHub Action: `fail-on-error: false`
- CircleCI Orb: `fail_on_error: false`
- Coverage Reporter (CLI): `--no-fail`
monitoring
We are experiencing an outage that appears to have originated at our infrastructure provider. We are unable to access our account and are working with our account manager to resolve the issue. Unfortunately, due to the nature of the incident, we have no way to establish an ETA.
We are doing everything we can to restore service, and will update our status page as soon as we have a fix or an ETA.
Please follow along here:
https://status.coveralls.io/
You can subscribe for email updates by clicking SUBSCRIBE TO UPDATES button in the top right corner of this page.
monitoring
We are continuing to communicate with our hosting provider around any updates or ETA.
monitoring
After a full day of working with our hosting provider's account team (who've been really helpful), we've discovered that this outage stems from an account restriction that, by all indications, shouldn't have happened (we believe the technical term is "snafu"). They are actively working to get it reversed.
This is not a technical failure — our infrastructure and all customer data are fully intact. Services will be restored as soon as account access is.
We're hopeful for resolution this evening or tomorrow morning. We'll have more to say once we're back online.
monitoring
As of 6am PST Thu, Feb 26, we are still waiting on restoration. We thought this would be resolved by this morning. We are in touch with our account team and are doing what we can to restore service. We apologize for the ongoing inconvenience.
monitoring
Day 3 | Evening
Status: Unresolved — No ETA
We want to be transparent with you: after two full days of working directly with our hosting provider’s account team, we still do not have an ETA for service restoration. Despite having internal sponsorship within our provider’s organization, we have been unable to get the traction needed to resolve what appears to have been an automated action, one that no one on their side has taken ownership of causing or fixing.
We understand the severity of this disruption. Your CI workflows depend on Coveralls, and we can see the impact this outage is having on your teams. That is not lost on us for a single moment.
This experience has made something painfully clear: no matter how trusted or established a cloud provider may be, a single vendor dependency without a failover plan is an unacceptable risk, for us and for you. We are already evaluating backup infrastructure options to ensure that nothing like this can take our service offline this way again. We’ll share more in our full postmortem.
In the meantime, to those of you who have stayed patient and stuck with us through this, thank you. We see you, we appreciate you, and we are committed to making this right. If there is anything we can do to help in the interim, please reach out.
We will continue to post updates as we have them.
monitoring
Day 4 | Morning
Status: Unresolved — No ETA
It's the morning of Day 3, and service has still not been restored. We want you to know we're here, fully aware, and have not stopped working on this.
We remain in constant communication with our hosting provider's account team, who we have every reason to believe is continuing to advocate for us internally. But the reality remains the same: we do not have an ETA, and we do not have direct control over the outcome we need: restoration of our services and access to our infrastructure.
As we pass milestones in this outage that we never imagined we would see (and haven't in 15 years of operation) the path forward is becoming clearer. We need to find a new provider, at minimum for failover, and potentially as our primary host. We've been reading the tweets, watching the YouTubes, and evaluating options. But if anyone in a position similar to ours has migrated away from a primary tier host and successfully manages a write-intensive service with hundreds of thousands of daily uploads, we would genuinely love to hear from you about your experience. Please reach out: [email protected]
Because if our services are not restored by the end of today, we will be standing up new infrastructure over the weekend.
We will continue to post updates as we have them.
monitoring
We are seeing systems coming back online. We assume service has been restored at some level.
We will assess and update you here ASAP.
monitoring
We are back, for at least some users.
We’ll stay at “partial outage” until we confirm full restoration.
monitoring
We would love to hear from anyone outside of the US as to whether service has been restored for you: [email protected]
We have no reason to believe service hasn't been restored to all regions, but we want to make sure.
We will continue monitoring.
monitoring
After 1-hour of monitoring, we are cautiously optimistic that service is fully restored in all regions.
Feel free to confirm service in your area (with thanks): [email protected]
And please let us know if you are still having any issues: [email protected]
We will continue to monitor throughout the rest of the day, and weekend.
Finally, please come back for our post-mortem. We are aiming for the first part of next week, but our priority is making sure service is stable.
For all of the kindness and support, we thank you.
To everyone, thanks for your patience. We'll be in touch.
resolved
This incident has been resolved.
postmortem
# Suspended for Not Paying—While Paying
_Latest update: Tuesday, Mar 24_
[This post-mortem is also available as a PDF](https://s3.amazonaws.com/assets.coveralls.io/statuspage/incidents/20260224/postmortem/Coveralls-Post-Mortem-Service-Outage-Feb-2026.pdf).
## Overview
On February 24, our hosting provider suspended our account. Our service was down for 68 hours. The stated reason was past-due charges. When we reached our account manager on the day of suspension, he reviewed our account and told us what he saw: an "account restriction" that, in his words, "shouldn't have happened."
Bizarrely, his review turned up an internal note claiming we'd made _no payments in six months_. That was demonstrably false and we provided immediate evidence to prove it.
We did have an outstanding balance—the product of a billing dispute that took nearly a full year to reach a decision in our favor. But finalizing what we owed required tracking down two credits we couldn't locate. We asked AR one specific question: _where did those two credits go?_ We asked it _six times_. For some reason we still don't understand, they simply stopped responding. We escalated to our account manager, who promised to intervene. Then we heard nothing from anyone. Until we were suspended.
Despite providing evidence of our payments, open billing cases, and relentless communication, we waited three days for our service to be restored. When someone finally acted, we were back online within minutes. Three days, and then minutes. Our provider has not explained that gap, or responded to the formal request for answers we submitted more than two weeks ago.
Without those answers, what follows is our account. We're sharing everything and letting you judge for yourself.
_If what you need most right now is assurance that this won't happen again, and to know what we're doing for affected customers, you can jump ahead to **What We're Doing** and **Making It Right**._
But we'd ask you to read through. On the surface, this looks like a company that didn't pay its bills and got suspended. The full picture tells a different story, and the evidence speaks for itself.
## About Coveralls
Coveralls has been providing code coverage analytics for 15 years. We're bootstrapped: no outside funding. Over 225,000 developers use [Coveralls.io](http://Coveralls.io) every day, and roughly 90% of them are open-source contributors who use the service for free. \[1\]
We have never experienced an outage like this in our 15-year history.
## The Incident
### What We Were Told About Suspension
More than once, over the past year, we asked our account manager directly whether we were at risk of suspension.
Each time, the answer was no. He told us suspension was designed to be rare, that it was reserved for accounts that had gone _delinquent_—stopped _paying_, and stopped _communicating_—and that it required his sign-off, _and_ his manager's.
He told us he received a regular list of at-risk accounts among those he managed, so he could review them and give feedback before any action was taken. He told us we had _never_ appeared on that list.
He said our provider _knew_ we were paying, and _knew_ we were actively communicating, with AR and with him. Based on everything he told us, suspension wasn't just unlikely, it wasn't supposed to be possible. At least not without warning.
### Timeline
**Tuesday, Feb 24 — Day 1**
1:45 PM PST: We suddenly lose access to our hosting provider's console. The service is still up, so we assume it's a technical issue. Multiple team members try their credentials. None work.
2:42 PM: We receive our first support request saying, "posting coverage data stopped working", but we don't see it until 2:51 PM due to the next event.
2:45 PM: A team member gets past a login screen and sees a message: "Your account was suspended because of past due charges." We don't believe it. We reach out to our account manager by email, then text, then phone. He confirms an "account restriction" that, based on his review of our account, "shouldn't have happened", and shares that an internal note on our account says, "_Customer has made no payments for 6 months_."
2:51 PM: We see the first support request.
2:52 PM: We open an incident on our status page. At this point, we are still expecting this to be reversed quickly and do not yet disclose the suspension publicly. In hindsight, we should have.
~3:00 PM: While we're on the phone with our account manager, one of us discovers the official suspension notification in our inbox, timestamped 2:03 PM, about 15 minutes after we were first locked out. Our AM asks us to create a new support ticket and promises to escalate. Two hours fly by while we feverishly collect and send evidence of improper suspension. We expect our AM to get this reversed as soon as he gets through to—_someone_.
5:36 PM: No definitive update. Our AM is "still working on it." He tells us the AR team involved is on Eastern time and may be gone for the day. We post that the issue has been identified and a fix is being implemented. We believe this. We are wrong.
7:28 PM: No resolution. Our account manager tells us he continues to escalate but that under the current circumstances, he himself has "limited access" to our account. Still—_should_ be fixed by morning. We update our incident, extend the outage window, and recommend fail-on-error: false for CI workflows.
~9:30 PM: Still no resolution. We check status throughout the night.
**Wednesday, Feb 25 — Day 2**
6:45 AM: We text our account manager, surprised service has not been restored.
9:48 AM: First public disclosure — outage originated at our infrastructure provider. We are unable to access our account.
5:56 PM: After a full day working with our provider's account team, we learn more about the restriction. Not a technical failure—infrastructure and data intact. Their team indicates they are working to reverse it, and we expect resolution by morning.
**Thursday, Feb 26 — Day 3**
6:53 AM: Still waiting. "We thought this would be resolved by this morning."
5:13 PM: After a full second day of trying to get answers as to why this is happening, and why it hasn't been resolved yet, the picture remains unclear. No ETA. "What appears to have been an automated action, one that no one on their side has taken ownership of causing or fixing." We commit to evaluating backup infrastructure and promise a full post-mortem.
**Friday, Feb 27 — Day 4**
7:41 AM: "As we pass milestones in this outage that we never imagined we would see \(and haven't in 15 years of operation\)..." We announce that if not restored by EOD, we will stand up new infrastructure over the weekend.
11:02 AM: Systems begin coming back online. We have not been told what changed.
11:11 AM: Service partially restored.
12:23 PM: After one hour of monitoring, cautiously optimistic that service is fully restored in all regions.
**2:30 PM: After two more hours of monitoring, the incident is officially marked resolved. Total outage: approximately three days \(68 hours\) across 4 calendar days.**
## What We Think Happened
Here's what we found when we started looking for answers:
### The Note That Wasn't True
The first thing we learned about why our account had been suspended was what our account manager told us: there was an internal note from AR that read:
> _Customer has made no payments for 6 months._
This was demonstrably false. Here is our payment history for that exact period—September 1, 2025 through February 24, 2026 \(the date of our suspension\):
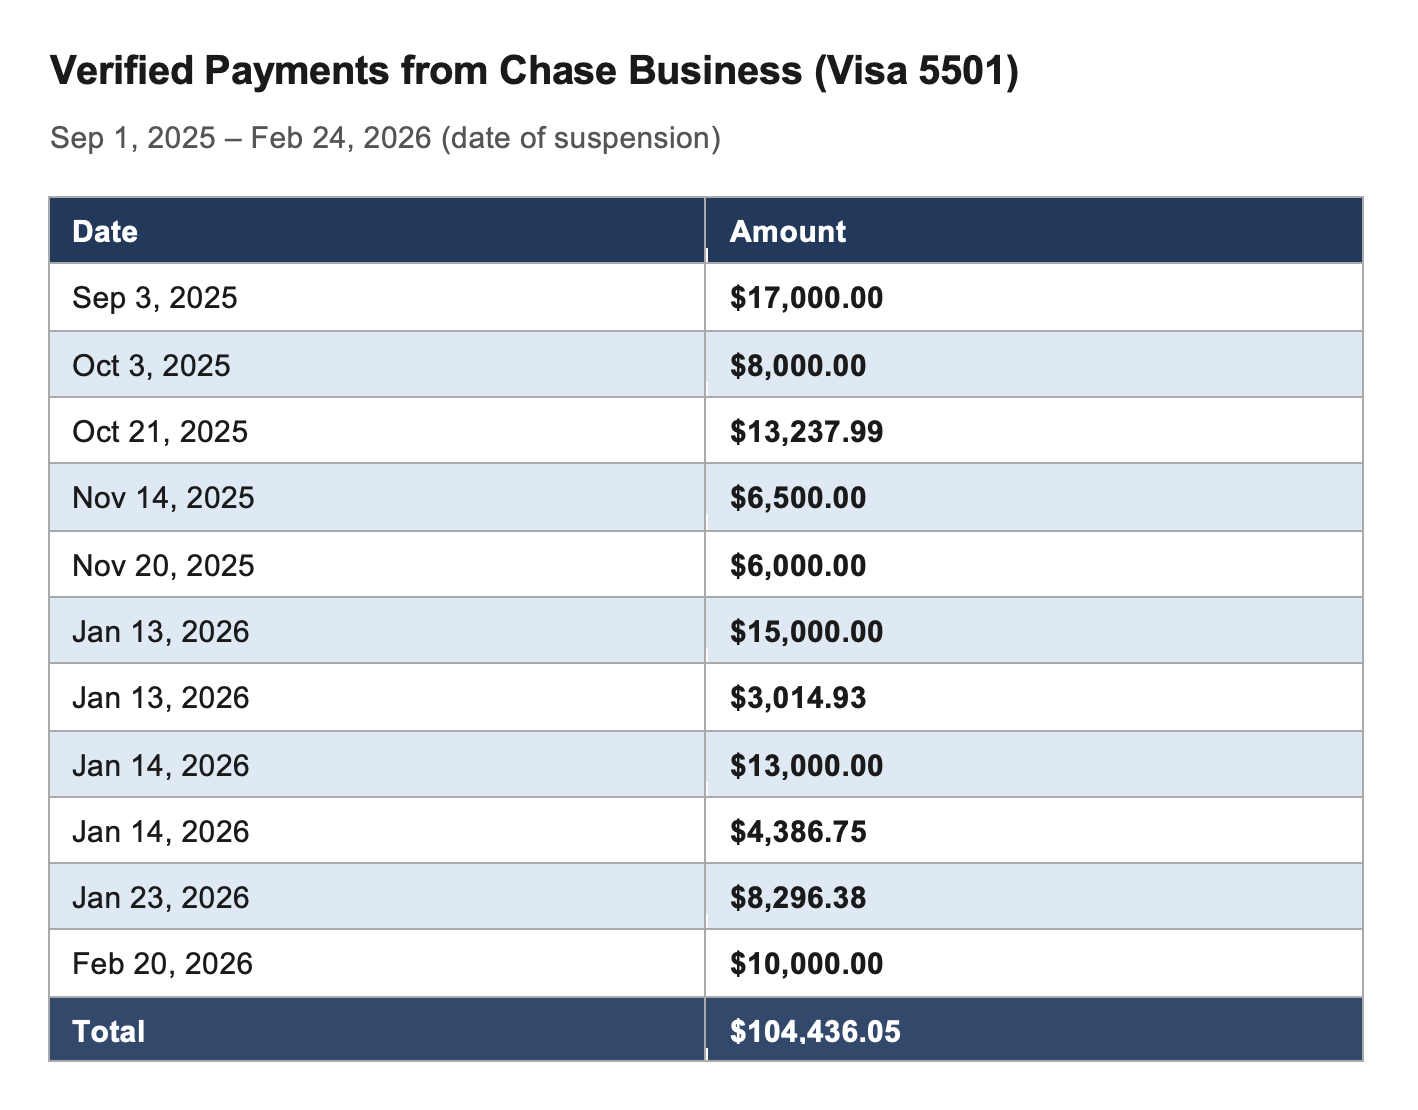
We shared this evidence with our provider immediately, backed by bank statements:
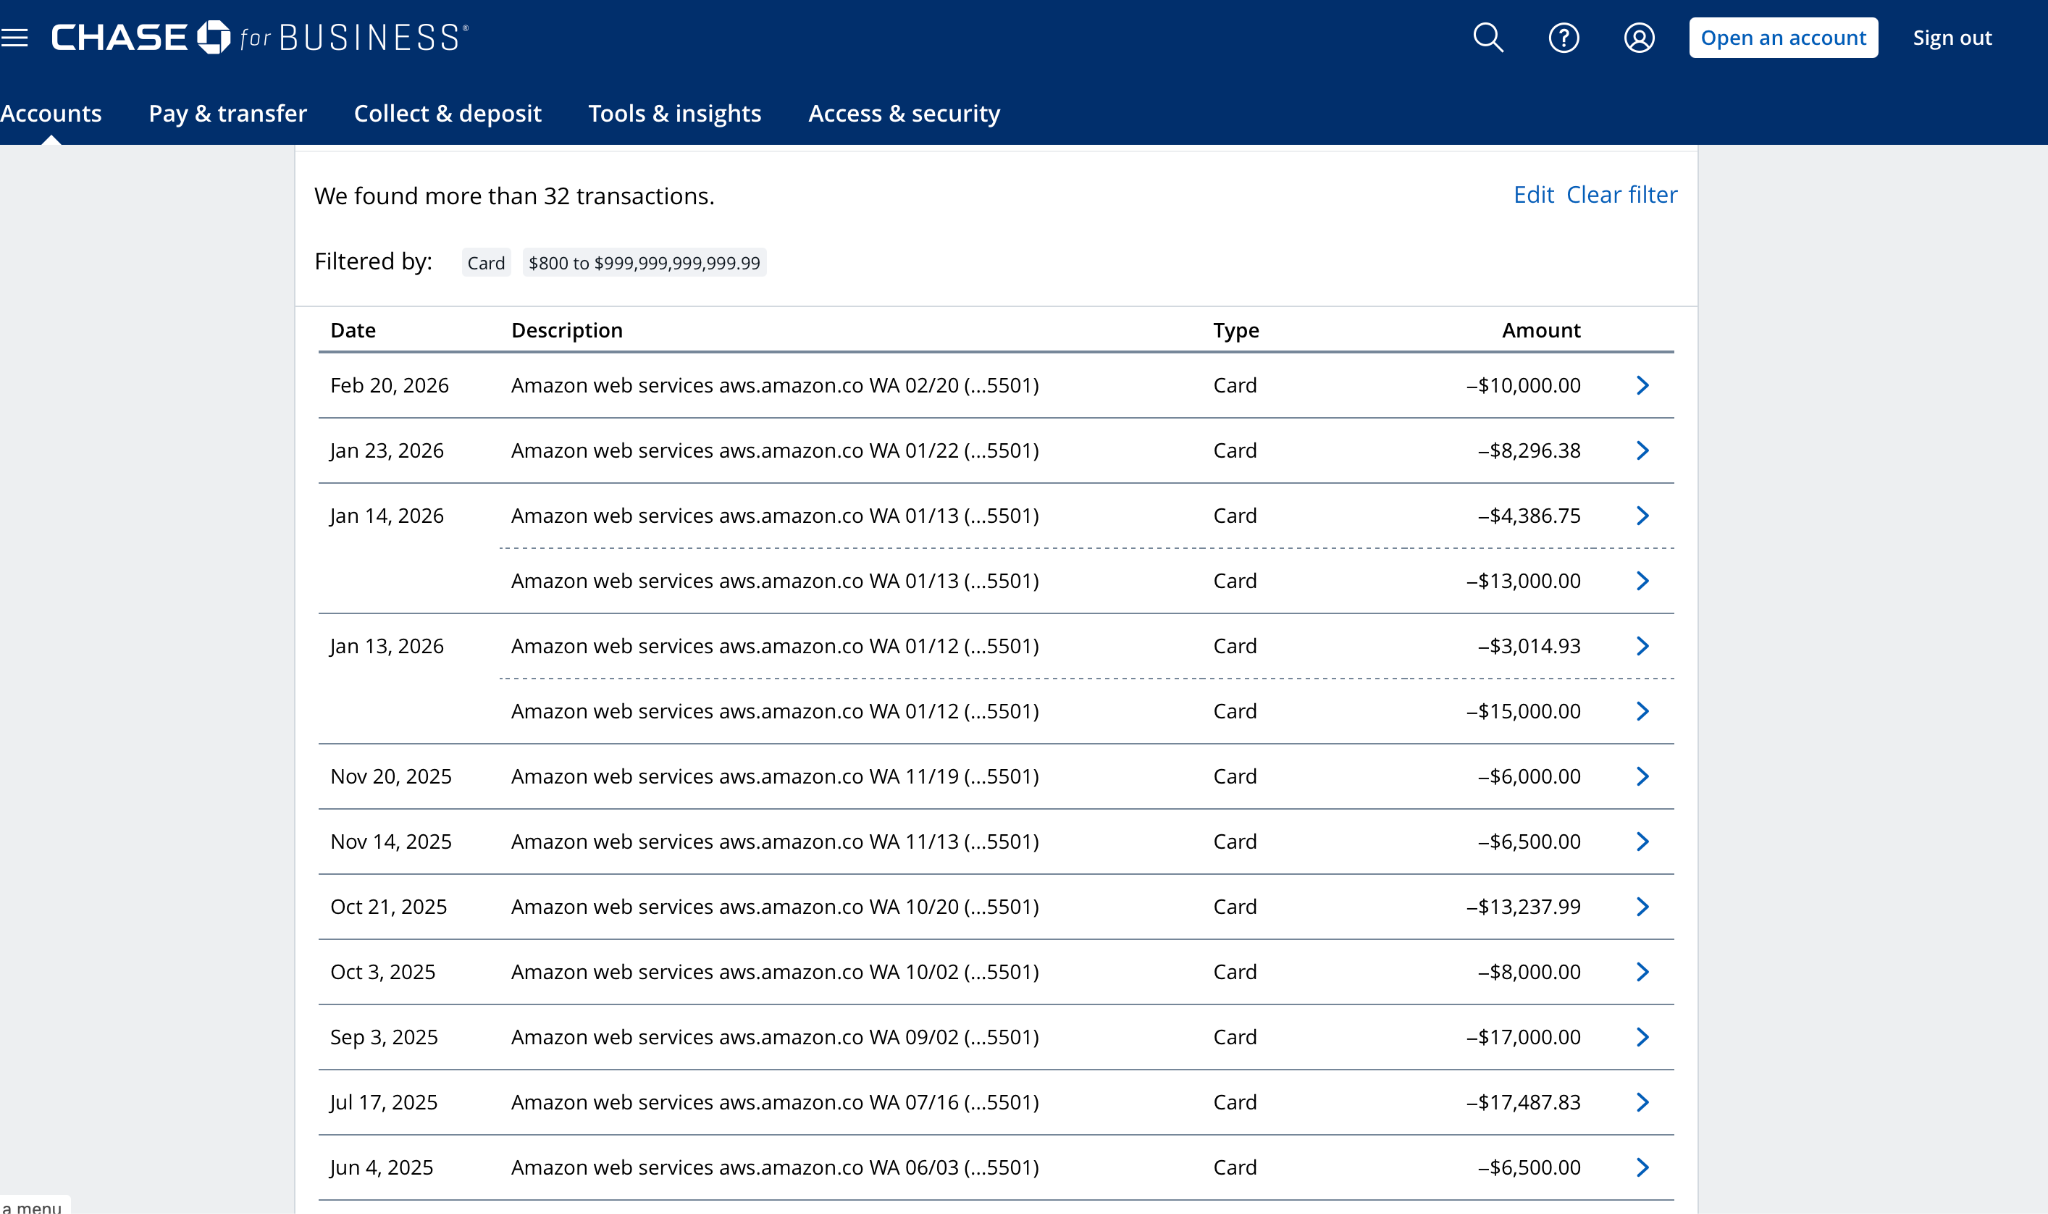
But it raises the question: if we were paying, why would our provider think we _weren't_?
### Why The Note Existed
When we look at our billing console we can see why someone might _think_ we hadn't paid: **it shows none of our payments**.
Invoices we know to have been fully paid show none of our payments against them.
Most notably, the **Transactions Tab** of the **Payments** section of our billing console contains _**no payment records**_ **for last 6 months**—resonating with that internal note:
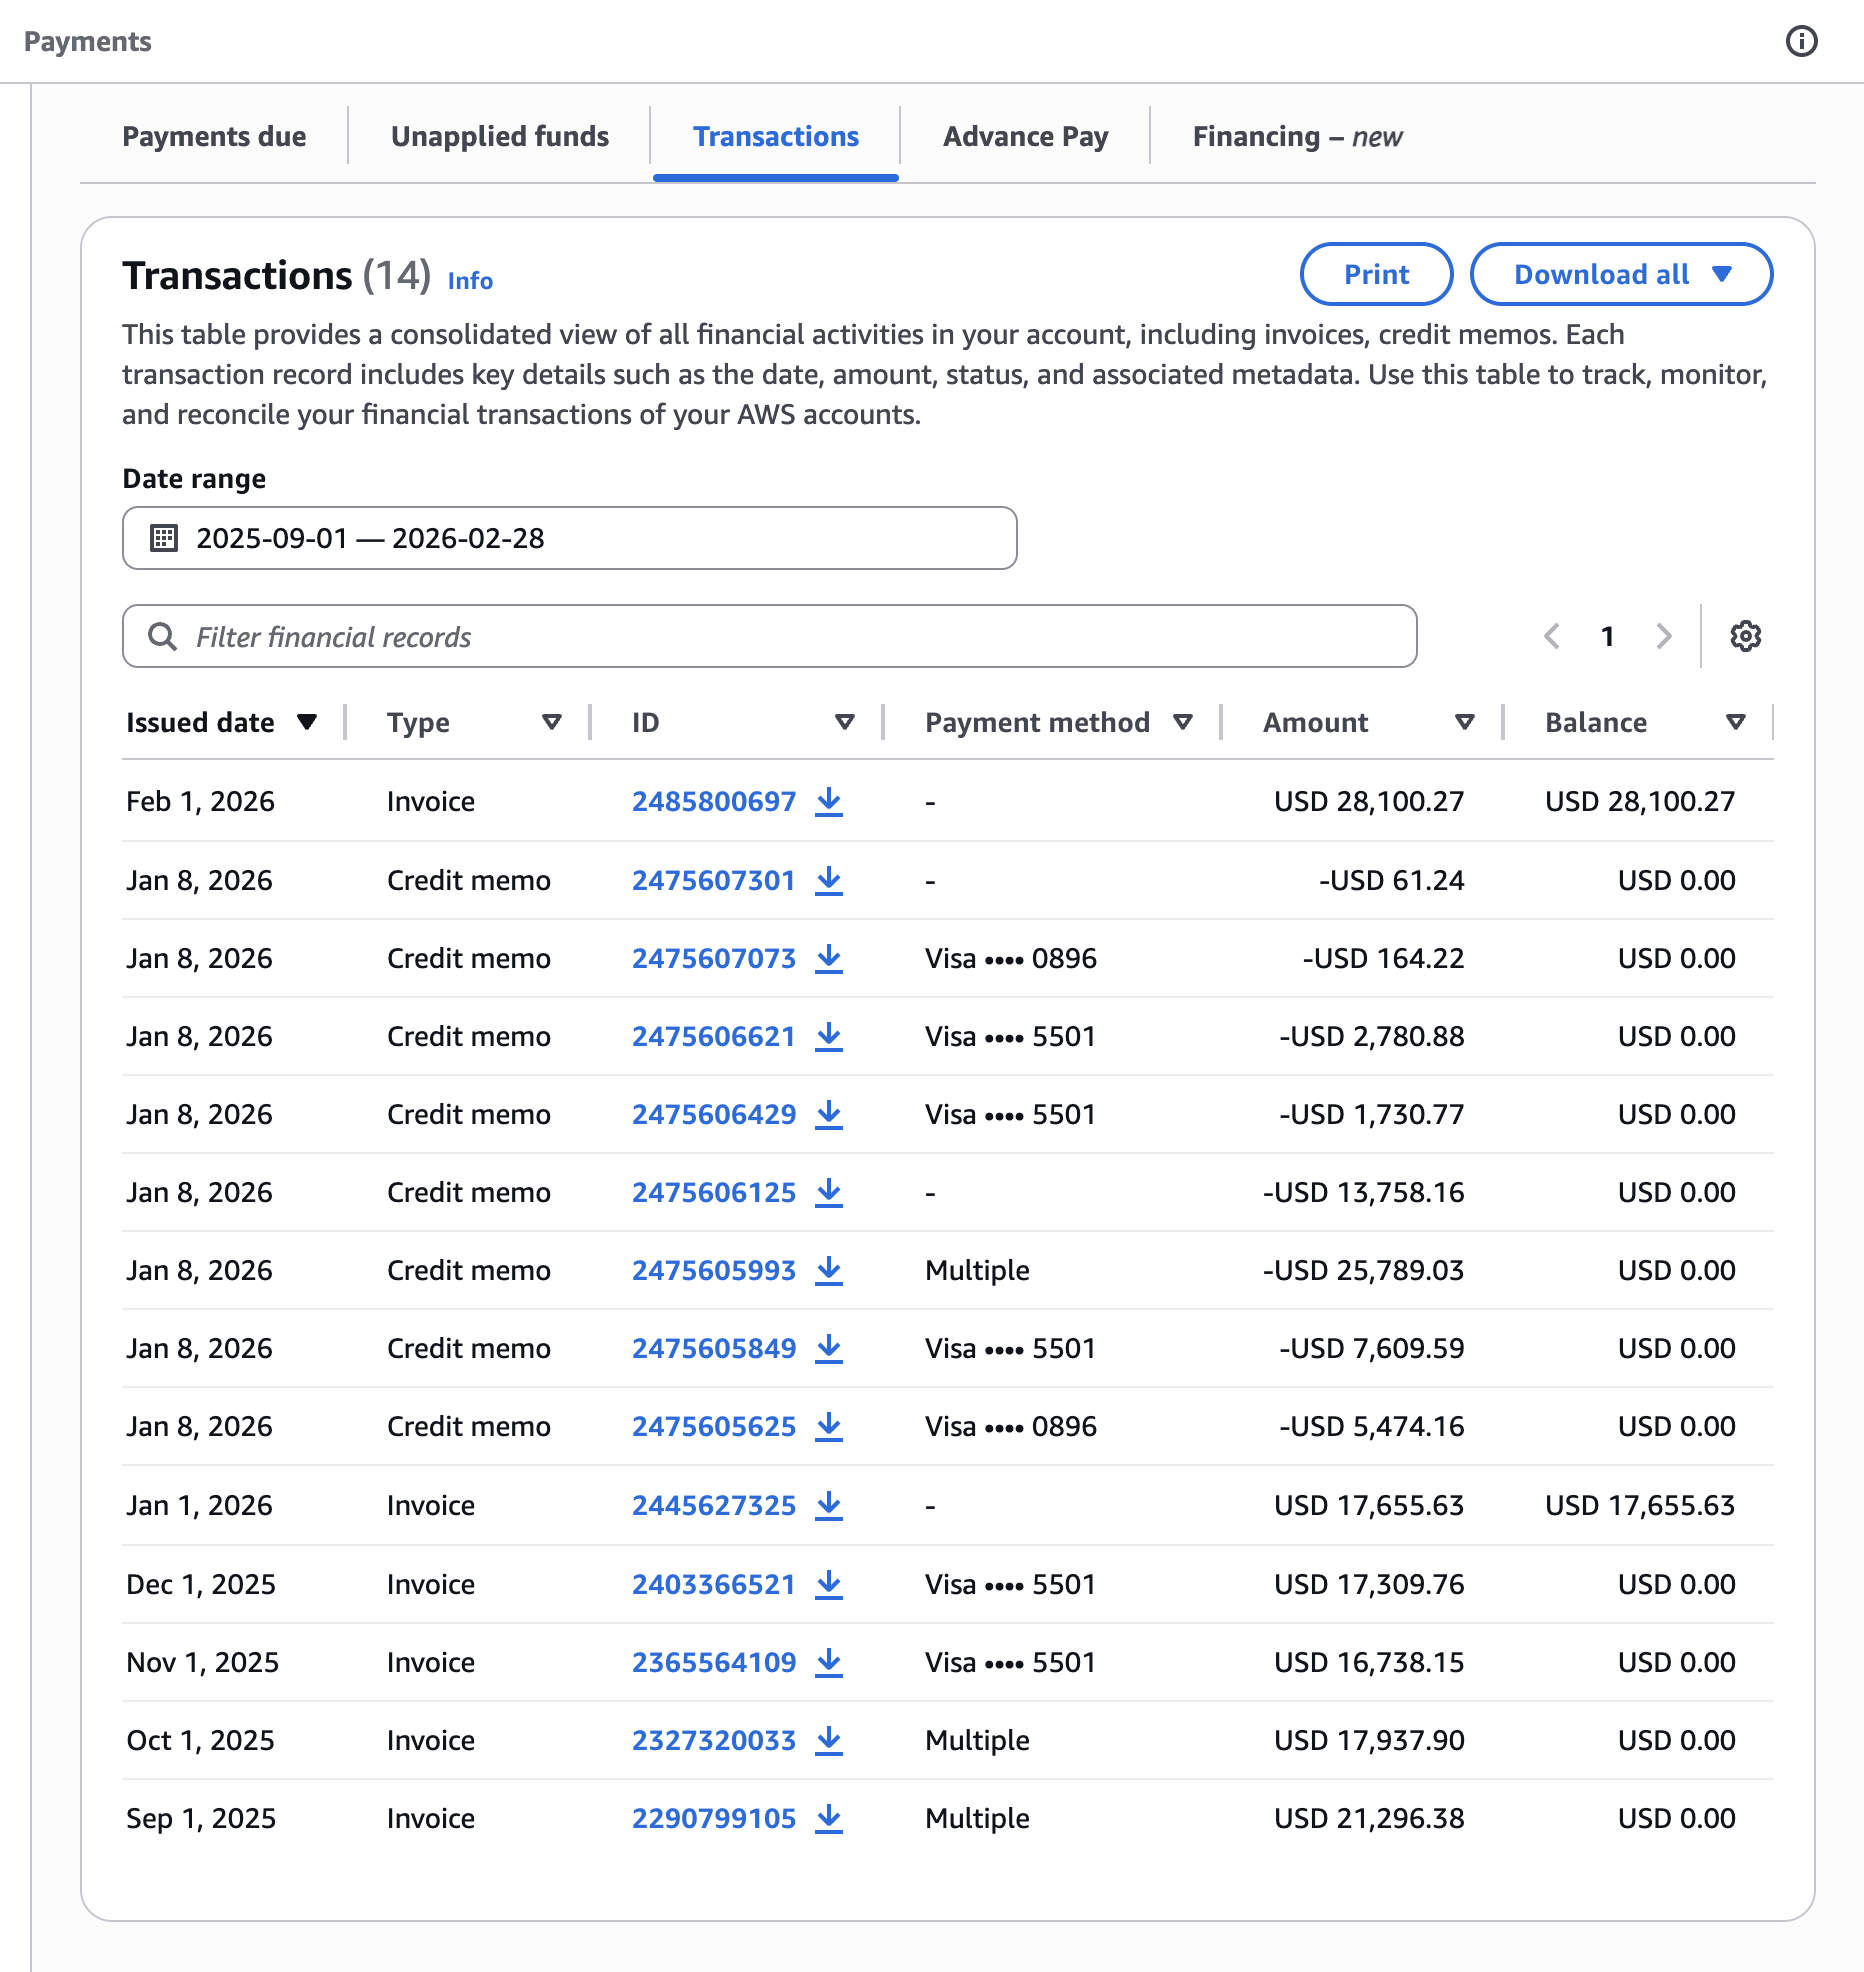
If an automated system relied on this same data to determine whether a customer had made payments, and that data showed six months of silence, it _might_ trigger exactly the kind of suspension we experienced: an automated action with no advance warning, with no one on their side able to explain it or willing to take ownership of it.
This is our strongest piece of evidence that the suspension was triggered by bad data, and not our actual account status.
—
To put this in context: over the six months during which the internal note claimed we'd paid _nothing_, our provider billed us $127,186. Our verified payments for the same period totaled $120,312—a gap of roughly $6,900, which is less than a third of the amount we were actively disputing in our second open billing case.
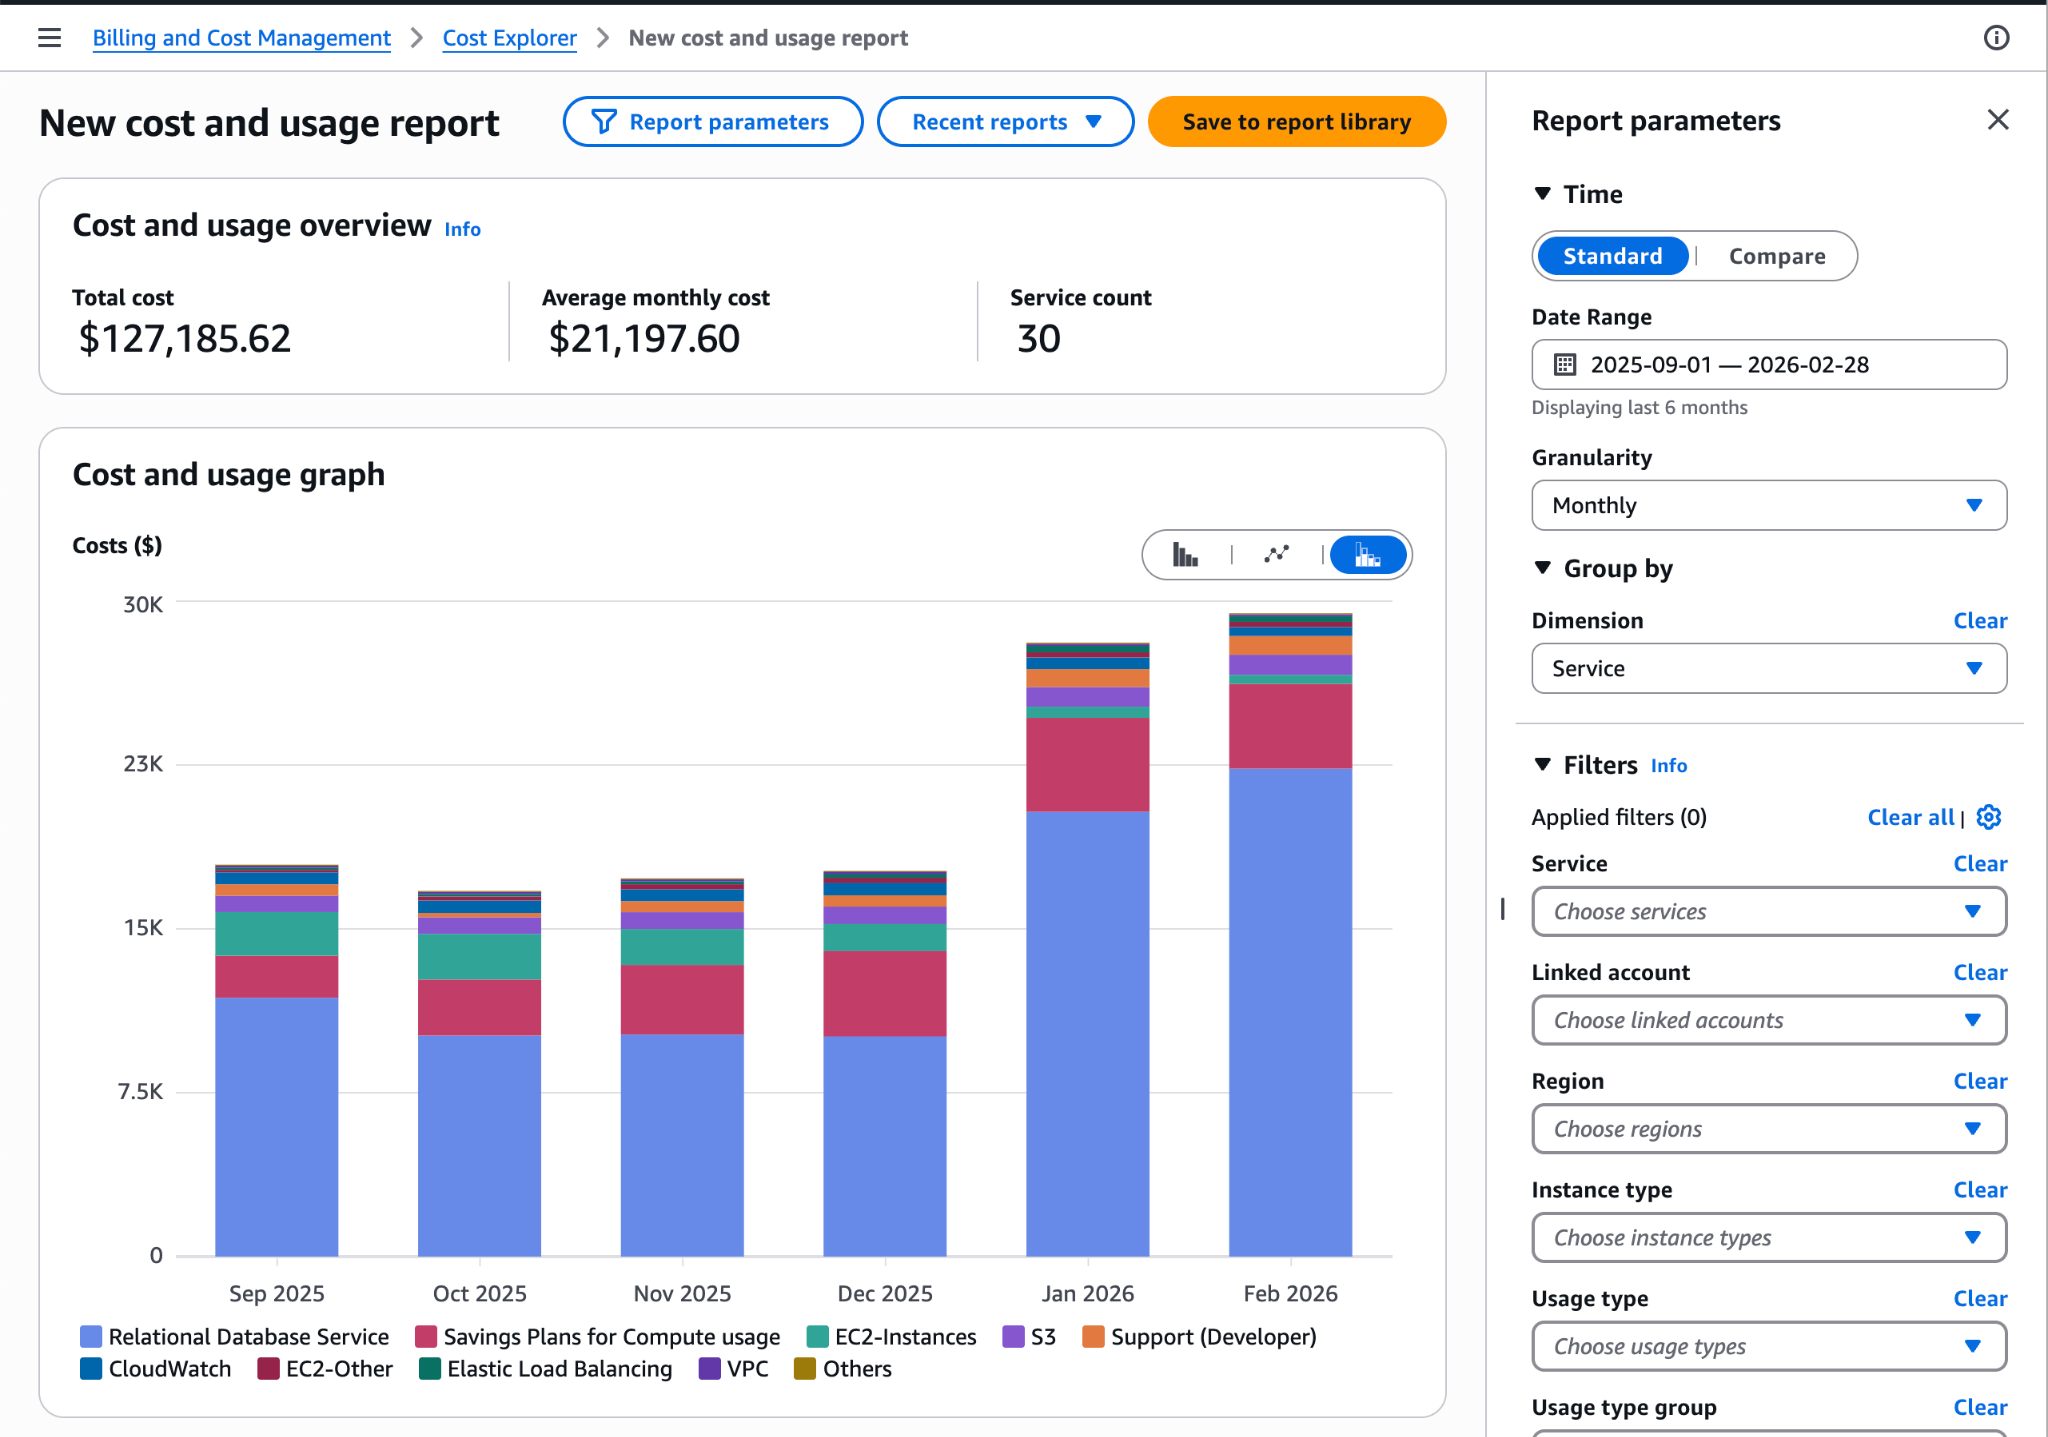
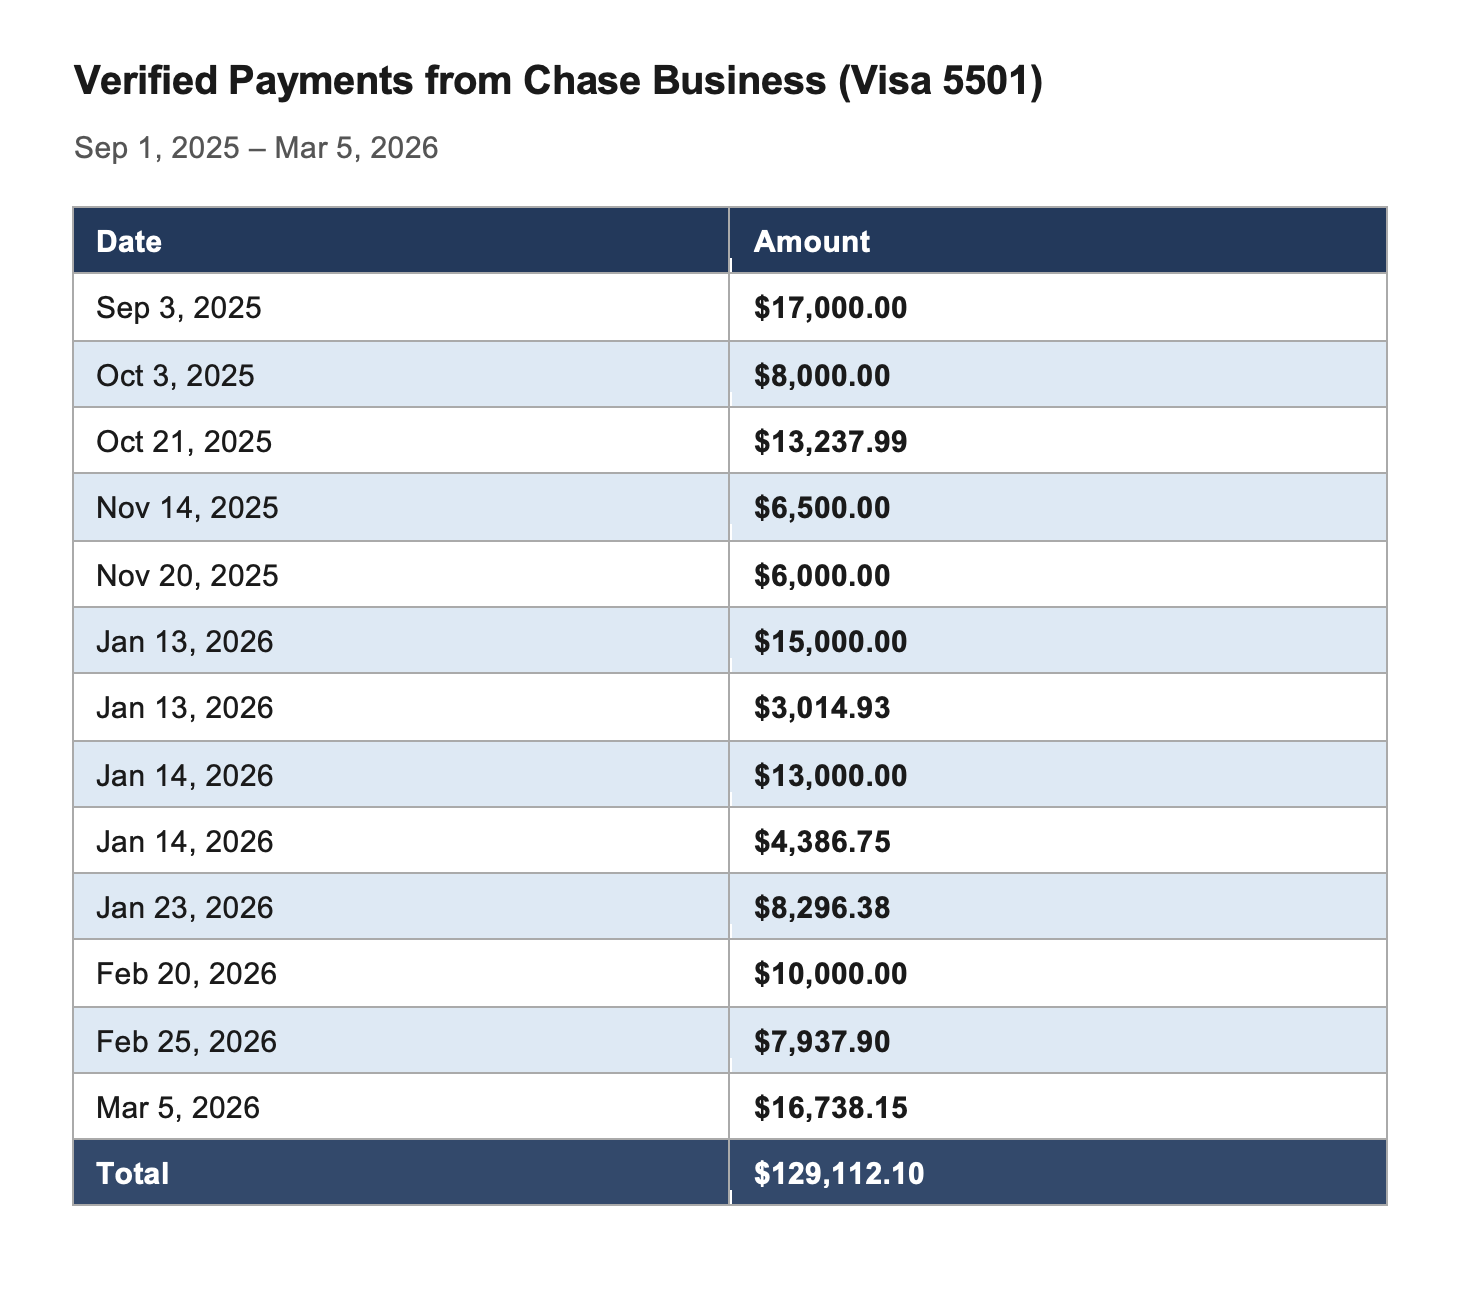
\(By March 5, our payments even exceeded our total invoiced charges for the period: we were not delinquent.\)
Our payments were in line with our usage. We weren't _up-to-date_—but the portion of the balance we still carried traced directly back to a single incident that triggered a billing dispute, which took ten months to resolve and still hadn't fully landed by the time we were suspended.
—
But the note, and the billing console, only explain so much. They might explain how the suspension was _triggered_. They don't explain why it took _three days_ to reverse, even after providing evidence of our payments and open billing cases. If there's an answer for that, it lives in the rest of the story. We've looked. We don't see a justification for either. Draw your own conclusions.
### How The Balance Happened
In 2025, we faced a critical infrastructure challenge. Our production PostgreSQL database, approaching a 65TB ceiling due to failing maintenance operations, also needed a major version upgrade before end-of-life. We started the upgrade a month early. It took four-and-a-half months to complete.
During three-and-a-half of those months, our provider levied Extended Support Fees on us that roughly _quadrupled_ our database hosting costs for that period. \[2\] We asked our provider to pause or waive them—the fees were simply beyond what we could absorb. They told us that wasn't possible, but that we could open a billing dispute and make our case. We did that, and our provider eventually approved credits for the full amount. But that process took ten months. \[3\]
During those ten months, those fees accumulated into a past due balance, so we asked AR for a repayment plan, and their answer was: wait. The credit outcome would affect what we owed, and they needed the case to resolve before we could finalize any repayment agreement.
In response to an email titled "Seeking repayment plan for past due balance," an AR representative told us:
> _Upon checking, the support case related to billing adjustment review via case ID remains active. Please continue to monitor the support case for any update and provide the required information for faster resolution. Once the billing adjustment review for re-appeal was completed, we can discuss for possible payment plan._
In the meantime, we paid what we could and waited for resolution. Our balance stayed on the books for ten months—and with it came past-due notices with threats of suspension we were told were automated and couldn't be stopped. Those are what prompted us to ask our account manager, more than once, whether we were truly at risk of suspension, and his answers gave us confidence that, difficult as the situation was, we were managing it the right way.
When those warnings arrived, we did the same thing: made a payment and notified AR. That pattern—always paying, always communicating—put us squarely in the playbook our account manager described, and it seemed to work because we never appeared on his at-risk list.
### A Balance We Couldn't Pin Down
When the billing case finally resolved in January 2026, we expected to finalize a repayment plan, but we were blocked _again_—and explaining why requires a brief note on how the approved credits worked:
The credits didn't arrive as a direct reduction to our outstanding balance. They came in eight different amounts, apparently as cash refunds—separate transactions that made their way back to us through different payment methods. This meant our balance didn't shrink by the amount of the credits as we expected it would; and, more importantly, some of the credits remained outstanding due to two transactions we couldn't locate. Whether and how _those_ had been applied—_unclear_.
Those two missing refunds had no payment method attached in our billing console, and we couldn't find matching deposits in any of our bank or card accounts. They were material to calculating our actual outstanding balance, and any repayment plan, and without AR's help, we couldn't track them down.
So we submitted our first request for help on February 12:
> _We are having trouble balancing our remaining amount due \($\[redacted\]\) against our credits awarded Jan8 \($\[redacted\]\). Can you help us track down these two \(2\) refund transactions? \[...\] We can't find a payment method associated with those two refunds \[...\] And we can't find matching transactions anywhere in any of our card or bank account statements. Do you know how / where those refunds were applied?_
Three days later, on Feb 15, we received a response that simply restated the information in our billing console. It didn't answer our question.
Within an hour of receiving it, we responded and made the stakes explicit:
> _Sorry if I wasn't clear: We have not been able to find these two refunds: \[...\] We cannot find the money. We believe we did not actually receive it. We have a general repayment plan in mind that we hope to present, but first we need to resolve this question of these two missing refunds. Without being able to account for that $\[redacted\], we believe our current outstanding balance could be off by that much. Your input on this is crucial for us._
We received no response.
Growing concerned about a possible disconnect with AR, that Friday, February 20, we cc'd our account manager on another follow-up to AR and, separately, forwarded the full thread to him directly, asking him to intervene:
> _Is there any way you can help us get a response from \[Redacted\] or someone else in Billing regarding the missing refund payments? We want to implement a repayment plan, but need to be clear on our numbers._
He replied the same day:
> _Yes — I'll reach out to her. \[...\] Let me pop into the ticket to see if I can escalate._
That was the last we heard from anyone.
On February 19, we received a past-due notice with a suspension warning dated the following day. This wasn't unusual—we'd received them throughout the entire ten-month period and had always responded the same way: we made a payment and notified AR. We made a $10,000 payment on February 20 and let AR know. We interpreted the passing of February 20 the way we always had: as confirmation that our payment had been received and the threat had passed.
Four days later, we were suspended.
### Six Weeks Before Suspension
Six weeks before our suspension, on January 14, we filed a second billing dispute. We had been trying to _reduce_ our hosting costs by shrinking our production database; instead, a mandatory storage configuration upgrade blocked us for 27 days and roughly _doubled_ our costs during that period. We disputed the incremental charges.
After working through all required questions, our request was formally submitted to Billing's specialist team:
> _Since these charges are not yet present on your account we here at Billing team cannot promise a refund or credits to offset these charges. However, we can connect with your AWS Account Manager for getting an exception approved for you by our specialist internal team. Please contact your Account Manager so they can work with the team for the required approval._
We formally looped in our AM as directed—he was already cc'd on the case, but we followed the process—and he confirmed he was actively monitoring and advocating for our credit request.
On January 22, we experienced a temporary account restriction—we were unable to add certain services needed for our workaround. We reached out to our AM and sent a parallel update to our AR contact, informing her of the open billing case and our AM's involvement. The restriction was lifted.
Our AR contact replied with direction nearly identical to what we'd received throughout our first billing dispute:
> _Kindly continue to monitor the support case for billing adjustment review._
The technical workaround we selected took 20 days—January 22 through February 10—spanning our two most recent billing periods.
When the effort was complete, we updated Billing, and our account manager, with the final timeline, cost, and the amount of our credit request. By February 12, everyone had the same information: the work was done, the dispute was submitted, and our last two invoices were under active dispute.
Based on prior experience and similar direction from AR, we believed charges under active dispute would not be counted toward our outstanding balance—let alone any balance used to justify suspension.
We don't know whether our disputed billing charges _were_ part of the outstanding balance that triggered suspension, or not. All we know is that AR knew about this open case, and so did our AM, who had told us more than once that he reviewed at-risk accounts before any suspension action was taken.
Neither warned us that suspension was imminent.
—
To recap: we were paying—over $100K during the same six months the internal note claimed we'd paid nothing. We were communicating—multiple messages to AR in the twelve days before suspension, plus a direct escalation to our account manager after AR went silent. We had an open billing dispute, and a repayment plan in progress with a specific blocker we had been asking AR to help us resolve for nearly two weeks.
None of the criteria our account manager described for suspension applied to us. We hadn't stopped paying. We hadn't stopped communicating. We had never appeared on his at-risk list. The suspension hadn't had his sign-off or his manager's.
On the day of our suspension, our account manager reviewed our account and told us it "shouldn't have happened."
Three days later, when someone finally acted, service was restored within minutes.
To this day, we still don't know exactly why the suspension happened, or why it took three days to reverse.
## Open Questions \(Our Formal Request for Answers\)
On March 4, three business days after our service was restored, we sent a formal request for answers to our hosting provider. As of this writing—fourteen days later—we have not received a response.
We're not publishing those questions verbatim here because we don't want to frame them as a public ultimatum. But our questions cover four areas:
We want to understand what triggered the suspension and who authorized it—whether it was automated or a human decision, and why we were suspended when we had never appeared on our account manager's at-risk list.
We want to know why our billing console showed no payment records for a period in which we had paid over $104K in verified bank transactions, and what prompted the internal note.
We want to know why our missing refund issue—raised six times between February 12 and February 24—was never substantively addressed before we were suspended.
And we want to understand why reinstatement took three days after we provided evidence of our payments, our open billing cases, and our multiple attempts to resolve the blocker to our repayment agreement—especially when service was restored in _minutes_ once someone finally acted.
We're committed to updating this post-mortem when we have those answers.
## What We've Learned
Two things we should have done differently, and one assumption we should never have made.
The process guidance our account manager provided was verbal. We relied on it in good faith—it was specific, consistent, and came from someone with direct knowledge of our account. But we never sought written confirmation. We should have.
We noticed discrepancies in our billing console earlier in this process. We flagged them but didn't fully understand their significance, or their potential connection to how our account might be evaluated—until it was too late to escalate effectively. That's a failure we must own.
And finally: we assumed we were safe. We were doing everything we'd been told to do. The most recent suspension warning had passed without incident—as others had. We interpreted that silence as confirmation. It wasn't. We should have insisted on written confirmation of our account status; and when we couldn't get AR to respond, we should have escalated beyond email and beyond our account manager.
—
That's our account of what happened. What follows is what we're doing about it.
## What We're Doing
The most significant thing we've done to prevent a recurrence is reduce our monthly database hosting costs by approximately 50% from their peak. We accomplished this by completing a major database project we'd been working toward for over a year—the same project that was blocked twice, producing the unplanned cost spikes at the center of both billing disputes. That pressure is gone. We can easily meet our regular charges going forward.
We have nearly paid off our outstanding balance—by 50% if disputed charges are included, by more if not—and we've already begun implementing our repayment plan. We met with our provider this week to formalize that, but we're not waiting to execute. If we prevail in our open billing dispute, the remaining balance shrinks further, making repayment that much easier and faster.
We are standing up failover infrastructure on a second provider, expected to be operational within 60 days. No single vendor should ever again have the ability to take our service offline with no recourse.
### Going Forward
Going forward, we will not rely on verbal guidance or implicit signals to determine our account standing. We will seek explicit, written confirmation of our status from both our account manager and a dedicated AR contact—someone we hope will commit, in writing, to direct communication \(not system warnings\) that gives us at least one opportunity to resolve any issue before adverse action is taken. We will also get in writing the exact steps our provider follows before suspending an account.
Finally, we owe you a commitment about how we communicate during incidents. During this outage, there were moments—particularly on Day 1—where we knew more than we shared publicly. We held back because we didn't fully believe what was happening, and because we kept expecting it to be reversed at any moment. That was the wrong call. Going forward, we will share what we know as soon as we know it, even when it's embarrassing, scary, and we don't yet have the full picture. You deserve that transparency in real time, not just in a post-mortem.
## Making it Right
Every paying customer affected by this outage will receive a credit equal to four days of their current subscription—one day for each day of interrupted service. This credit will be applied automatically to your next bill.
We understand that's not enough—it's an attempt to be equitable while not harming ourselves more than we've already been harmed by this outage. We want you to know that if anyone feels it doesn't properly compensate for how the outage affected you, just reach out and we will refund the whole month. No questions asked.
To our open-source users: the best we can offer is this post-mortem. We know some of you have been through similar things. If it's helpful for you to discuss further, please reach out. We'd also be grateful to hear from anyone who's been through something similar and what you did about it from a hosting perspective. And thanks for the HugOps. We're ready to share some back now.
If you have questions about anything in this post-mortem, we're at [[email protected]](mailto:[email protected]).
## Acknowledgments
Finally: thank you.
During the worst week in our 15-year history, our community showed up. Customers offered server rack space. An SRE director offered to apply pressure through his own provider relationships. People we'd never met sent messages of support and solidarity.
In the DevOps community, the term is: HugOps. We received a lot of it that week, and it made a real difference.
For those who've stayed with us through this—thank you. We know you have other options. We appreciate the opportunity to make this right.
—
## Notes
\[1\] _That ratio matters for this case. Our revenue doesn't scale proportionately to our infrastructure costs. Unexpected cost spikes hit us harder than they would a company whose hosting bill is covered by proportional revenue, which is part of why the billing situation at the center of this story developed the way it did._
\[2\] _AWS RDS Extended Support Fees \(ESF\) are charged per vCPU per hour on any RDS instance running a PostgreSQL major version past its end of standard support date — on top of normal instance costs. Our production instance was a db.r6g.16xlarge: 64 vCPUs, 512 GB RAM, at the 65TB maximum RDS storage allocation. At 64 vCPUs and the Year 1 ESF rate, the surcharge approached the cost of the instance itself. Our Major Version Upgrade — which took four and a half months, three and a half of which fell within the Extended Support window — required a Blue/Green Deployment, meaning we ran two db.r6g.16xlarge instances simultaneously for that entire period, each accumulating ESF charges around the clock. Two instances at normal cost plus ESF on both: that is what nearly quadrupled our database hosting costs for the period._
\[3\] _Note: In connection with the credit award, we signed an agreement that restricts us from disclosing specific amounts or characterizing our provider's position on the dispute._
—
[Download a PDF version of this post-mortem](https://s3.amazonaws.com/assets.coveralls.io/statuspage/incidents/20260224/postmortem/Coveralls-Post-Mortem-Service-Outage-Feb-2026.pdf).
All Systems Operational
시작 2026년 2월 2일 오후 5:33 UTC · 0m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
resolved
Just a note to address the gap in our Coverage Calculation Background Job Dequeue Time Graph today, MON, FEB 2 from 00:15:00 PST to 07:35:00 PST:
Coveralls experienced no disruption in service at this time. Instead, a deployment issue cause the cron job that reports the metric to fail until it was resolved at 07:35:00 PST.
Elevated Latency in APAC and EU
시작 2025년 12월 19일 오후 2:34 UTC · 50m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
identified
We are continuing to experience elevated latency in APAC and EU.
monitoring
We are continuing to monitor as we scale to clear backlogged jobs.
resolved
We had to pause some queues to recover performance for new jobs, but will clear those as soon as we've recovered normal build times for new jobs (ETA: 15-min).
If you are a user in APAC or EU, you may have had your jobs paused. One repo in particular has represented 90% overnight workload. We will reach out to that user.
Elevated Latency in APAC and EU
시작 2025년 12월 18일 오후 2:51 UTC · 2h 7m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We had an incident overnight that entailed several server outages affecting APAC and EU users. The impact has been latency in recent build times for those users. We have resolved the issue and are scaling to clear backlogged background jobs. US Central and West users should not be affected.
monitoring
Update:
- Normal build times have been recovered for all new jobs.
- Backlogged jobs are 80% cleared (20% remaining).
We will continue clearing backlogged jobs until cleared and monitoring for any further issues.
resolved
Build times are normal for all new builds. Background queues have been cleared of 99% of backlogged jobs; the only ones that remain are for large repos (>5K source files), which should clear in the next 30-45 minutes depending on size.
No further effects on latency expected.
Closing this incident.
Elevated Latency
시작 2025년 11월 17일 오후 4:35 UTC · 3h 9m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We received reports from EU customers of elevated latency and have resolved the cause. We will be managing workloads to ensure standard processing times for all new builds, and scaling resources to clear delayed builds.
Follow this incident for updates.
monitoring
Build times are returning to normal for all builds created since 05:00AM PDT. Older builds are being processed by scaled resources and should clear in 45min to 1 hr.
If you are having issues with a slow or stuck build, especially if priority, feel free to reach out to us at [email protected]. These steps will save time:
1) Mention this incident:
https://status.coveralls.io/incidents/hkqt790213m5
2) Share your Coveralls Build URL (from your CI build log), or your CI build number.
resolved
This incident has been resolved. Build times for all new builds is normal across the board.
We are still clearing a backlog of background jobs, which should be clear in the next 15-20-min.
If you are having issues with a slow or stuck build, feel free to reach out to us at [email protected]. These steps will save time:
1) Mention this incident:
https://status.coveralls.io/incidents/hkqt790213m5
2) Share your Coveralls Build URL (from your CI build log), or your CI build number.
Elevated Latency
시작 2025년 11월 10일 오후 4:14 UTC · 2h 42m
Issues경미한 인시던트
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
We are currently investigating this issue.
investigating
We are continuing to investigate this issue.
identified
The issue has been identified and a fix is being implemented.
identified
We have confirmed elevated latency for global users in ASIA, AU and EU starting on Mon, Nov 10 around 09:15a UTC (01:15a PDT).
We have resolved the cause but will be performing RCA in the next 24-48 hrs to understand the triggering conditions and avoid further incidents.
In the meantime, we will be monitoring latency and will likely manage workloads to improve latency for new jobs (from currently active time zones), routing jobs from inactive time zones to new resources to clear the backlog.
We will upgrade performance from Degraded to (Fully) Operational when complete.
resolved
We have attempted to improve latency this morning for new jobs from users in EU and US time zones, which has meant offloading older jobs to specialized queues with scaled up resources, which, at this point, have already drained.
System-wide, latency continues improving for all users and should reach normal in 15-30 minutes for most users.
If you are still experiencing elevated latency after that, or have any jobs from CI builds run in the last 24 hrs that have not completed, please reach out to us at [email protected] and we'll investigate to determine whether your builds were caught up in this incident, or if they have a different cause.
NOTE: Missing data points in the "DEQUEUE" Graph on our main Status Page does not indicate that processing stopped during that period, just that the server that reports our stats lost comms during that period. As stated elsewhere, to avoid this confusion in the future it's one of our goals to spread stats collection across all servers.
504 Gateway Timeouts (Resolved)
시작 2025년 10월 24일 오후 6:35 UTC · 3h 19m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We received reports of 504 Gateway Timeouts from our Web Servers (coverage report uploads) between 6:00am-6:20am PDT and several moments ago between 11:15am-11:30am PDT.
We have recovered service to all web servers and are monitoring for further occurrences.
resolved
We are closing this incident having received no further reports of 504 errors today. We will continue to monitor for them.
Some reports of 504 Timeouts
시작 2025년 10월 13일 오후 6:02 UTC · 5h 13m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We have received some reports of 504 errors this morning. We are monitoring to avoid further occurrences.
We are looking into any gaps in our new monitoring regime, which has drastically reduced occurrences, to see where we can further improve.
resolved
We have received no further reports of 504 timeout errors on coverage report uploads today, but we continue to monitor and will continue trying to improve our mitigations.
504 Timeouts (Resolved)
시작 2025년 10월 10일 오후 3:23 UTC · 3h 37m
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We've received results of 504 Timeout errors from 7am PDT through 8:15am PDT. We have addressed the issue and issue was resolved as 8:19am PDT.
We are monitoring for further issues.
monitoring
Based on the details of today's incident, we've added another layer of monitoring that should give us earlier indications of this error state and allow us to respond more quickly.
resolved
This incident is resolved.
We have applied an additional layer of monitoring that should help us catch these cases earlier.
504 Timeout Errors on Coverage Uploads
시작 2025년 9월 26일 오후 3:28 UTC · 3d 0h
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
All systems operational.
During our US overnight hours (PDT / GMT-7), we received additional reports of 504 timeout errors affecting coverage uploads. The issue has since been resolved, and we are actively monitoring for further occurrences.
We have already implemented several mitigations over the past few weeks, and additional measures will be deployed today to further reduce the likelihood of these errors, particularly for our international customers.
If you experience a 504 error, the most helpful details you can provide are:
1. A timestamp or timeframe of the error
2. Any Cloudflare Ray ID shown on the error page
Please share these details in our public tracking issue here:
https://github.com/lemurheavy/coveralls-public/issues/1824
These reports are invaluable as we continue to investigate and refine our mitigations.
resolved
We are closing this incident after recent mitigations and a weekend without any reports.
We continue to implement mitigations and infrastructure changes we believe will further reduce incidents of this error type.
Elevated 504 Timeout Errors
시작 2025년 9월 3일 오후 6:00 UTC · 21d 6h
Pending
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
monitoring
We’re currently seeing elevated reports of 504 Timeout errors affecting some customers on a subset of Coveralls pages, including:
- Source File pages
- Repo pages
- Add Repos pages
All systems and pages are generally operational; a subset of customers are experiencing these errors, sometimes intermittently.
There is a public tracking issue for the Source File timeout errors here:
https://github.com/lemurheavy/coveralls-public/issues/1757
Fix in progress:
We’re implementing a short-term fix over the next 24–48 hours, which should eliminate the timeouts.
A longer-term fix is also planned, but will roll out over several weeks, but early phases of that implementation should also reduce the request times that were originally triggering the 504 timeouts.
What you can do:
If you're currently affected, we recommend following updates here, and subscribing to the public issue: https://github.com/lemurheavy/coveralls-public/issues/1757
If your issue pattern differs from above, or you suspect a different root cause, reach out to [email protected], and we'll verify for you.
monitoring
We are still working on a near-term fix. We will post here, and here when complete:
https://github.com/lemurheavy/coveralls-public/issues/1757
monitoring
All systems operational.
Continuing to keep this open until we have released our short-term fix into production.
Subscribe for updates at this status page, or follow this public tracking issue for updates:
https://github.com/lemurheavy/coveralls-public/issues/1757
monitoring
All systems operational.
We have released one of two parts of a near-term solution into production resolving a minority subset of 504 errors. We are still working on releasing part two into production.
Subscribe for updates at this status page, or follow this public tracking issue for updates:
https://github.com/lemurheavy/coveralls-public/issues/1757
monitoring
All systems operational.
Earlier today (6:45–7:45 AM PDT), we received elevated reports of 504 timeout errors. We have not been able to reproduce the issue since, but if you are still experiencing errors, please contact us at [email protected].
The affected areas may include:
- Coverage Report Uploads (/api/v1/jobs)
- Add Repos Page
- Repo Page
- Source File Page
Fixes for the Add Repos, Repo, and Source File pages are scheduled to be deployed by end of day (PDT).
monitoring
Mitigation in place.
All systems operational.
This morning we deployed additional capacity and autoscaling measures to reduce 504 errors on coverage report uploads:
- Doubled our web server fleet (on top of the prior doubling when this issue began).
- Enabled autoscaling at the web layer, allowing the fleet to double again automatically when NGINX response times exceed thresholds.
The underlying trigger remains rare surges of upload requests from outlier repositories (750–1250 uploads per build). While we have paused processing for these repos, our HTTP servers must still handle the incoming requests until they stop.
Timezone coverage:
As a small team based in Los Angeles (PDT), our ability to respond in real time is most limited overnight (10p–6a PDT). Unfortunately, the primary outlier repos are in APAC, making this the window of highest risk. With these changes, we hope to reduce the occurrence of upload 504s during this window.
We will monitor results closely and continue tuning autoscaling thresholds. Please let us know if you continue to see 504 errors on uploads.
monitoring
Mitigated – Monitoring
All systems operational.
Recent mitigations, including fleet expansion and autoscaling, have reduced 504 timeout reports significantly. The remaining reports are infrequent and occur mostly during overnight and weekend hours (PDT).
We are continuing to monitor closely and are working on a multi-part solution to eliminate all known causes. Until then, we are keeping this incident open in Monitoring. We will close it once 504 errors have returned to being unexpected, isolated events.
monitoring
Fix for unrelated 500 errors:
If you receive a `500` error with this error message format:
> ⚠️ Internal server error. Please contact Coveralls team.
Please know it is unrelated to the `504` errors being monitored in this open incident.
Those, intermittent `500` errors are caused by a regression in one of the latest coverage-reporter releases: `v0.6.16` or `v0.6.17`.
Workaround:
Pin your coverage-reporter-version to `v0.6.15` in your integration config.
For thorough instructions, see this public issue:
https://github.com/coverallsapp/coverage-reporter/issues/180
We’re investigating the root cause and will post updates once a fix is released.
resolved
500 Internal Server Errors on Uploads
The recent 500 error surfacing during some coverage uploads as:
> ⚠️ Internal server error. Please contact Coveralls team.
has been resolved. A full postmortem will be published here soon. In the meantime, you can find more detail in the main tracking issue:
https://github.com/coverallsapp/coverage-reporter/issues/180
Summary
The root cause was ultimately infrastructure-related, not a regression in recent coverage-reporter releases. The previous workaround of pinning your coverage-reporter version is therefore not required.
We have decided to close this incident, which we intentionally kept open for over a week to track a series of 504 and 5xx issues with overlapping root causes. In hindsight, the broadened scope made updates less clear than we'd hoped. With today’s resolution and the mitigations applied throughout the week, the occurrence of 504 errors during uploads (POSTs) has been significantly reduced. Going forward, any new 504 errors should be considered unexpected, isolated events.
At the same time, we continue work on several instances of intermittent GET-related 504 errors affecting:
- Source File pages
- Repo pages
- Add Repos pages
Progress on those issues will be reported separately here:
https://github.com/lemurheavy/coveralls-public/issues/1757
postmortem
**This is a postmortem on this specific issue:** Intermittent 500 Errors on Coverage Uploads
**Summary**
Between September 20–24, some customers experienced intermittent `500 Internal Server Error` responses during coverage uploads \(`POST /api/v1/jobs`\). The issue was initially hard to diagnose because:
* Failures did not surface reliably in our error tracker \(BugSnag\).
* They appeared to affect only some requests, some customers.
**Impact**
* Some coverage uploads failed to process, causing build reporting delays or gaps.
* Frequency was low enough to appear intermittent, which delayed detection and resolution.
**Timeline**
* **Sep 20–23**: First customer reports of intermittent 500s. Initial theories involved a regression in a recent release of our coverage-reporter integration \(client-side\).
* **Sep 23–24**: Deep log analysis across ELB and application logs revealed errors concentrated on a single web server.
* **Sep 24**: Confirmed that server alone was responsible for thousands of SSL-related failures \(`Faraday::SSLError`, `OpenSSL::SSL::SSLError`, `Seahorse::Client::NetworkingError`\). Other servers were clean.
* **Sep 24**: Mitigation: that server was destroyed. Errors ceased immediately.
**Root Cause**
In terms of possible cause, we believe this additional Web server was provisioned during autoscaling with a different Ubuntu version than the rest of the fleet. This seemed to result in a broken or outdated CA certificate store, causing outbound SSL connections \(GitHub, Travis, etc.\) to fail intermittently—but then bubble up to a `500` error for the original request \(`POST` to `/api.v1/jobs`\).
**Resolution**
* Problematic server removed from service.
* Future mitigation: verify baseline OS/version and CA store when adding new servers, especially via automation.
* Next step: document the correct procedure to disable a single server in Cloud66 load balancers, instead of outright destroying, so we can retain the server for forensic investigations.
**Lessons Learned**
* Errors can hide if they don’t surface in the bug tracker. Direct log analysis is essential.
* Even one misconfigured server can cause significant customer impact.
* Consistency in OS/base image, and CA, is critical.
More reports of “Website under heavy load”
시작 2025년 8월 20일 오후 3:48 UTC · 6h 33m
Issues경미한 인시던트
영향을 받은 구성 요소
Coveralls.io APICoveralls.io Web
investigating
We are currently investigating this issue.
investigating
We are continuing to investigate this issue.
identified
The issue has been identified and a fix is being implemented.
monitoring
A fix has been implemented and we are monitoring the results.
resolved
We have implemented an intermediate solution and believe this issue has been resolved for now. To fully resolve the root cause, we will need to implement a more long-term solution, which is currently in design. (Please read postmortem for more information.)
In the meantime, we will be doing our best to monitor for spikes in traffic from outlier repos and manually respond where our intermediate solution may not mitigate as much as we hope it will.
postmortem
We believe this issue has been resolved for now.
The underlying cause still appears to be large spikes in incoming Web traffic from other outlier repositories that we have not yet identified or not yet paused.
**Interim Solution**:
To reduce the risk of recurrence, we have applied _temporary load balancer adjustments_ that change how requests are distributed, which should _lower_—if not _eliminate_—the frequency of **503** “**This website is under heavy load**” **errors**.
**Permanent Solution**:
We are also designing a permanent solution to _rate-limit abnormal request patterns_. This will require coordination at the policy/SLA level before it can be fully implemented.
In the meantime, we will continue to closely monitor traffic and use targeted load balancer and web server configurations to mitigate the impact of outlier traffic spikes.
**More details**:
For a more detailed assessment / RCA of this incident and its recent, related incidents, see [this postmortem](https://status.coveralls.io/incidents/wqbsxnzv0jsf).
**Update \(Thu, Aug 21\)**:
We have identified a **different permanent solution**, which does not entail changes to SLA-level details for “outlier repos.” We may still implement such a solution, but our alternative solution should avoid further 503 errors and be implemented in the next 48-72 hrs.

